
AI server hosting offers dedicated, high-performance computing infrastructure, typically comprising bare-metal servers equipped with powerful GPUs. Our bare metal GPU servers provide the robust, scalable, and secure environment you need to train, refine, and deploy AI applications for the maximum competitive edge. Experience the power of top-of-the-line GPUs for your AI models. Get AI models and tools such as DeepSeek or Ollama running on our dedicated GPU servers and tag us on Hugging Face for a shout-out of your favorite Projects. GDPR. RedSwitches AI dedicated servers are architected from the ground up to support artificial intelligence workloads. Our infrastructure. Virtualization in CloudKleyer is based on the open source solution Oracle VM VirtualBox. This allows you to run multiple Windows, Linux or Oracle Solaris operating systems on a single physical machine. Contact us to rent a custom GPU dedicated server. Whether deploying generative AI applications, deep learning pipelines, or inference workloads, the right configuration balances performance against expense.
[PDF Version]
AI-driven data centers evolve from single-chip to heterogeneous multi-GPU architectures. High-speed optical interconnects enable scalability, while silicon photonics and co-packaged optics boost bandwidth and energy efficiency amid modular, ecosystem-based competition. NVIDIA's latest AI platforms—including B200, B300, GB200, and GB300—introduce cluster interconnect designs that combine NVLink fabrics, high-performance NICs, and large-scale switching networks. This article explores how these technologies work together, from node-level GPU communication to. Intra-rack interconnects primarily address communication requirements within a single server rack, connecting multiple compute nodes (servers) or accelerator resources inside the rack. Shift from single‑node to. With low latency, massive networking bandwidth, and all-to-all connectivity, the sixth generation NVIDIA NVLink™ and NVLink Switch are designed to accelerate training and inference for faster reasoning and agentic AI workloads. The sixth-generation NVLink enables 3. This shift is pushing optical interconnect.
[PDF Version]
AI servers are high-performance computing systems designed to process complex artificial intelligence workloads, including large-scale model training and real-time inference. Some enterprises look for the very latest models, while others achieve the same results by selecting proven, widely available refurbished systems at a lower cost. Indeed, the AI server market was valued at $38. 3 billion in 2023 and is estimated by Global Market. Building your own AI server isn't just a technical project, it's a bold step toward empowering yourself with flexibility and independence.

An A100 server typically refers to a server-grade system built around NVIDIA's A100 Tensor Core GPUs. These powerful, integrated systems are designed for the most demanding AI, data analytics, and High-Performance Computing (HPC) workloads. The NVIDIA Ampere Architecture, which powers the A100. Build, train, and deploy machine learning models using the NVIDIA HGX A100 or A100 PCIe on demand with Vultr Cloud GPU. I agree to the. While newer chips push peak speeds, the A100 offers the perfect balance of enterprise reliability, massive VRAM, and cost efficiency — available in both 40GB and 80GB variants.

Think of MCP like a USB-C port for AI applications — it provides a universal way to connect AI models to different data sources and tools. Standard input/output (STDIO) – AI Assistant launches the MCP server as a subprocess and exchanges data through standard input and output. Refer to PySDK Installation for details on how to install PySDK. Create a directory for the local model zoo You'll need to create a directory to hold your. To connect Cursor to Port's remote MCP, follow these steps: Go to Cursor settings, click on Tools & Integrations, and add a new MCP server. This lets you reuse existing MCP servers or. By the end of this guide, you'll know how to connect your backend MCP server to ChatGPT, define tools, register UI templates, and tie everything together using the widget runtime.
[PDF Version]
A complete tutorial for building a production-ready AI inference server on dedicated GPU hardware. The Model Context Protocol (MCP) is reshaping how AI applications connect to the world. Introduced by Anthropic in November 2024, MCP provides a standardized, open-source framework for Large Language Models (LLMs) to interact with external tools, data sources, and workflows. Covers framework selection, deployment, API design, monitoring, security, and scaling. While integrating a single ChatGPT API call is straightforward, running hundreds of AI agents in production, each potentially costing thousands of dollars. Design high-performance model serving systems that deliver consistent AI capabilities at enterprise scale. Prerequisites: This guide assumes familiarity with Kubernetes (pods, deployments, CRDs), basic GPU infrastructure concepts, and REST API design.
[PDF Version]
Models like the Asus Creator, ASRock Taichi series (AMD), or any Z790 board (Intel) are good choices. RAM: 32GB or 64GB DDR4/DDR5 depending on your workload. Dual-channel configurations are generally. AI servers accelerate model training and real-time inference, delivering powerful computing with CPUs, GPUs, and specialized AI accelerators. Their scalable and efficient architecture enables businesses to run AI workloads faster and more effectively. AI servers provide powerful compute for. This guide provides a detailed technical comparison of the leading workstation platforms: Intel W790 (for Xeon) and AMD's WRX90 / TRX50 (for Threadripper PRO). We analyze slot layouts, power delivery, memory channels, and remote management features to help you select the correct foundation for your. This article explains the internal PCB composition of an AI server by disassembling the server hardware, so readers can gain a clearer understanding of the PCB types and their relative value within a system.
[PDF Version]
This article presents a layered framework that systematically outlines the entire chain—from chips, HBM, packaging, and interconnects, to data centers, power supply, and networks, and ultimately to inference services and enterprise governance. Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best. That's the job of an AI server—a custom-built system that keeps AI applications fast, scalable, and efficient. An AI server's architecture is all about. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before. Indeed, the AI server market was valued at $38. Electronic components, such as capacitors, filters, antennas, diodes.
[PDF Version]
Effective rack lighting selection requires you to balance brightness specifications, installation methods, and energy efficiency to achieve optimal server visibility. Target 400-500 lumens per fixture with 4000K color temperature for enhanced contrast and reduced eye strain. Unlike overhead lighting, rack lighting addresses blind spots inside enclosures and ensures technicians. We at PacLights understand that proper rack lighting transforms server room operations. The right lighting system reduces troubleshooting time by up to 40% while preventing costly equipment mistakes. They can be functional so you can actually see inside your server rack, especially when using a closed server rack. Basically, it sets up the flux_led support, identifes the RGB LED strip, configures HA to ping google DNS every 2 minutes, then the state/color of the lights will change depending if the internet is up or down. Most racks follow EIA-310 and TIA-942 standards for compliance. SeamLine Batten fits narrow corridors. Hot/cold aisle containment and.
[PDF Version]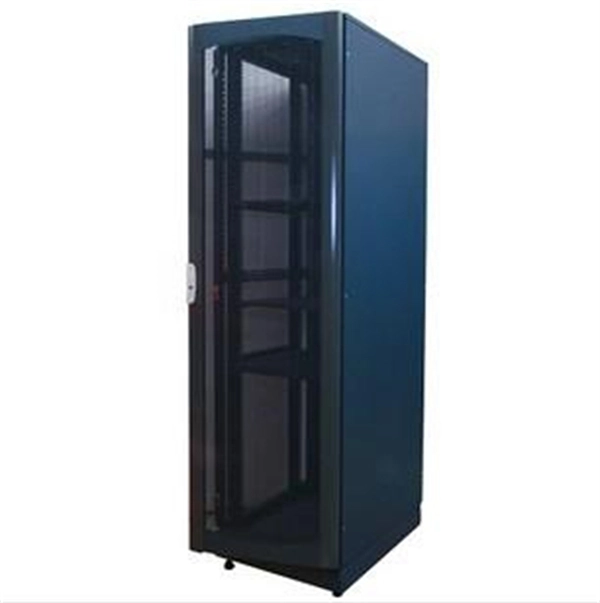
This article explains what GPU servers are, why they matter for AI and how teams can access GPU compute through cloud platforms, dedicated instances, bare-metal servers or hybrid setups. Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best. That's the job of an AI server—a custom-built system that keeps AI applications fast, scalable, and efficient. Unlike full-scale LLM deployments, task specific AI workloads don't need. The new Cisco UCS X580p GPU node with UCS X-Fabric delivers GPU-dense performance, scalable fabrics, unified management, and supports NVIDIA RTX Pro 4500 and 6000 Blackwell Server Editions GPUs. Testing conducted by Dell in July of 2024. Performed on PowerEdge XE9680 with 8x Nvidia H200 GPUs and XE9680 with Nvidia H100 GPUs. 1 Llama2. Dell's AI Factory platform (e. PowerEdge XE97xx/XE9712) provides high-density rack-scale clusters (72 GPUs per rack with NVLink, ~30× LLM inference speed-up and up to 25× energy efficiency advantage over prior-gen systems ()) with both liquid- and air-cooled options.
[PDF Version]
Using advanced optical modules boosts AI system speed and bandwidth, helping handle large data loads with low delay and high efficiency. Understanding their role is key to building efficient, scalable AI systems. Optical modules convert electrical signals into light to move data quickly and reliably in. High-quality optical modules play a crucial role in this process, providing stable high-bandwidth and low-latency links for training and inference tasks, and effectively reducing data transmission error rates in large-scale clusters. This article systematically explains how optical modules build an efficient and stable interconnection system for intelligent. Optical modules, also known as optical transceivers, are crucial components in optical communication devices, primarily used for converting electrical signals into optical signals for transmission and then converting received optical signals back into electrical signals.
[PDF Version]
Dell, HPE, Lenovo, and Supermicro are riding record AI server demand, but winning enterprise customers requires more than just Nvidia chips. With GPUs standardized around Nvidia, vendors compete on AIOps, liquid cooling, and deployment services as enterprises ramp up inference. Artificial Intelligence (AI) server manufacturers have experienced surging demand as data center operators require significantly more computing power than before the advent of ChatGPT and other Generative Artificial Intelligence (Gen AI) tools. Enterprises are seeking solutions that can handle complex workloads, from machine learning training to real-time inference. These massive computing needs have given rise to a. The global AI server market is expected to be valued at USD 142. 83 million by 2030 and grow at a CAGR of 34. (US), Hewlett Packard Enterprise Development LP (US), Lenovo (Hong Kong), Huawei Technologies Co. From GPUs that can crunch insane amounts of data to infrastructure that can stretch and grow as needs change, these companies are building the backbone that keeps AI ticking.
[PDF Version]
The next generation of AI servers pushes the bounds of computational power at the cost of increasing power consumption, requiring the use of liquid cooling. This forces servers to slow down (a process called throttling) or even shut down completely. We will dive deep into liquid cooling technologies. Direct-to-chip and immersion. Advanced AI chips are generating more heat in data centers, necessitating improved cooling solutions. These servers are equipped with input and output piping and require an ecosystem of manifolds, CDUs (cooling distribution) and. Schneider Electric's data center liquid cooling solutions are purpose‑built for AI workloads, GPU servers, and high‑density IT environments. Collecting heat and rejecting heat efficiently is the key to saving energy, decreasing time to value, and lowering total.
[PDF Version]
Server rack ventilation is a big deal when you want to keep the temperature right in a data center. Ventilation is more than just moving air in and out; it involves managing airflow, adjusting the room layout, and choosing the right. Do you always need professional cooling systems such as water cooling, or is simple network cabinet ventilation sufficient? We believe that every situation requires an individual solution. If you don't have enough ventilation, servers can overheat. After all, sealing these gaps (both within and along the sides of cabinets) often provides the greatest return on investment of any airflow management effort, both. Excess heat is one of the most significant risks to server room performance, and the foundation of preventing it is proper ventilation. Without controlled airflow, temperatures can rise rapidly, putting hardware at risk, reducing efficiency, and increasing operating costs. Additionally, positioning the rack in a cool environment and using blanking panels can further.
[PDF Version]
SoftBank Corp has initiated discussions with US chip giant Nvidia and Taiwanese manufacturer Foxconn to develop a domestic production system for artificial intelligence servers. The plan, reported by Nikkei, signals a significant move to strengthen Japan's technology infrastructure. Fujitsu begins domestic manufacturing of sovereign AI servers in March 2026 at its Ishikawa factory. 🛡️ In the age of AI, who controls the servers. However, the release on November 30, 2022, of the ChatGPT chatbot and virtual assistant took the IT world by storm, making GenAI a household term and starting off a stampede to develop AI-related hardware and software. The project. Artificial intelligence (AI) is being adopted across all industry sectors and the growing need to run AI (as well as machine learning, or ML) workloads is placing considerable demands on servers. 3 billion in 2023 and is estimated by Global Market.
[PDF Version]
Implement hot aisle/cold aisle containment, use blanking panels to block unused rack space, and ensure perforated floor tiles align with equipment intakes. Maintain at least 3 feet of clearance around racks for airflow. As data center densities increase, efficient cooling solutions become crucial for maintaining optimal operating conditions. Filtered Fan. A single high-density rack (10kW+) can generate as much heat as a small space heater, and without a tailored server rack cooling solution, this concentrated thermal load leads to hot spots, server throttling, hardware failures, and costly downtime (averaging $100,000 per hour, per Gartner). 1 Impact of Heat on Server Lifespan and Performance Electronic.
Contact us for competitive quotes on any of our fiber optic products
Get a Quote