
This article explains what GPU servers are, why they matter for AI and how teams can access GPU compute through cloud platforms, dedicated instances, bare-metal servers or hybrid setups. Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best. That's the job of an AI server—a custom-built system that keeps AI applications fast, scalable, and efficient. Unlike full-scale LLM deployments, task specific AI workloads don't need. The new Cisco UCS X580p GPU node with UCS X-Fabric delivers GPU-dense performance, scalable fabrics, unified management, and supports NVIDIA RTX Pro 4500 and 6000 Blackwell Server Editions GPUs. Testing conducted by Dell in July of 2024. Performed on PowerEdge XE9680 with 8x Nvidia H200 GPUs and XE9680 with Nvidia H100 GPUs. 1 Llama2. Dell's AI Factory platform (e. PowerEdge XE97xx/XE9712) provides high-density rack-scale clusters (72 GPUs per rack with NVLink, ~30× LLM inference speed-up and up to 25× energy efficiency advantage over prior-gen systems ()) with both liquid- and air-cooled options.
[PDF Version]
As an indispensable core component in AI servers, inductors are widely used in multiple critical modules, with key functions including energy storage, signal filtering, noise suppression, and voltage regulation. These inductors are the result of Cyntec's proprietary technologies, which encompass everything from material formula. AI workloads are accelerating demand for high-performance power delivery in servers. VRMs must stabilize power to GPUs/TPUs with growing thermal and efficiency constraints. For example, the NVIDIA H100 GPU can exceed 700W under full load, pushing multi‑phase VRMs to use high‑efficiency inductors to. Inductors for AI servers by Application (Cloud Computing, Automotive Electronics, Industrial Automation, Other), by Types (Surface Mount Device, Dual In-line Package), by North America (United States, Canada, Mexico), by South America (Brazil, Argentina, Rest of South America), by Europe (United. The Inductors for AI servers Market was valued at USD 2. 09 billion in 2025 and is projected to reach USD 2. This growth trajectory is supported by the increasing demand for AI-driven applications and the rising need for efficient power management.
[PDF Version]
Think of MCP like a USB-C port for AI applications — it provides a universal way to connect AI models to different data sources and tools. Standard input/output (STDIO) – AI Assistant launches the MCP server as a subprocess and exchanges data through standard input and output. Refer to PySDK Installation for details on how to install PySDK. Create a directory for the local model zoo You'll need to create a directory to hold your. To connect Cursor to Port's remote MCP, follow these steps: Go to Cursor settings, click on Tools & Integrations, and add a new MCP server. This lets you reuse existing MCP servers or. By the end of this guide, you'll know how to connect your backend MCP server to ChatGPT, define tools, register UI templates, and tie everything together using the widget runtime.
[PDF Version]
This essential guide covers the difference between SFP, SFP+, and QSFP, explains speed classifications (1G, 10G, 400G), and details key buying factors like DOM and third-party compatibility. What Is an SFP Module and What Role Does It Play in Network . Selecting the correct SFP module is not simply a matter of matching connectors. In modern Ethernet networks, choosing the wrong transceiver can result in link failures, speed mismatches, compatibility errors, or unexpected distance limitations. This guide helps network engineers and data center professionals understand essential technical specifications, evaluate. SFP (Small Form-factor Pluggable) is a compact, hot-pluggable network interface module used to connect network devices (switches, routers, firewalls) to fiber optic or copper cables.
[PDF Version]
800G AOC is the standard interconnect solution for AI clusters such as the NVIDIA DGX SuperPOD, supporting low-latency, high-bandwidth communication for gradient synchronization and parameter exchange between GPUs, thereby resolving network bottlenecks in large-scale model training. An 800G AOC (Active Optical Cable) is an integrated high-speed cable that combines optical transceivers, DSP signal processing chips, and fiber links end-to-end. Our transceivers (200G. Acquisition will bring industry-leading Silicon Photonics PIC technology in-house, expanding Credo's addressable market and deepening its optical interconnect portfolio across 800G, 1. Credo's 800G 2xDR4 ZeroFlap (ZF) optical transceivers give network operators the ability. To meet the requirements of today's network engineers, Integra Optics has introduced a new lineup of 800G optical transceiver products, specifically designed for hyperscale and high-performance computing applications. It directly transmits electrical signals through passive or active copper wires without the need for photoelectric conversion, offering advantages of.
[PDF Version]
A distribution box , also known as a power distribution box or electrical distribution box, is used to distribute electrical power safely to multiple circuits. It helps organize, protect, and control electrical connections in residential, commercial, and industrial. Understand the key differences between distribution boards and boxes—functions, applications, safety, cost, and when to use each one. They may sound similar, but they have different roles in electrical. In the world of electrical systems and power distribution, the terms distribution board and distribution box are often used interchangeably, which can cause a lot of confusion, and at LED Controls, we understand that! Still, while they both play a vital role in managing electrical circuits and. If the hardware is identical, why do we have three different names? The answer is simple, but profound: An electrical box is defined by its mission, not its material.
[PDF Version]
This article presents a layered framework that systematically outlines the entire chain—from chips, HBM, packaging, and interconnects, to data centers, power supply, and networks, and ultimately to inference services and enterprise governance. Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best. That's the job of an AI server—a custom-built system that keeps AI applications fast, scalable, and efficient. An AI server's architecture is all about. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before. Indeed, the AI server market was valued at $38. Electronic components, such as capacitors, filters, antennas, diodes.
[PDF Version]
AI-driven data centers evolve from single-chip to heterogeneous multi-GPU architectures. High-speed optical interconnects enable scalability, while silicon photonics and co-packaged optics boost bandwidth and energy efficiency amid modular, ecosystem-based competition. NVIDIA's latest AI platforms—including B200, B300, GB200, and GB300—introduce cluster interconnect designs that combine NVLink fabrics, high-performance NICs, and large-scale switching networks. This article explores how these technologies work together, from node-level GPU communication to. Intra-rack interconnects primarily address communication requirements within a single server rack, connecting multiple compute nodes (servers) or accelerator resources inside the rack. Shift from single‑node to. With low latency, massive networking bandwidth, and all-to-all connectivity, the sixth generation NVIDIA NVLink™ and NVLink Switch are designed to accelerate training and inference for faster reasoning and agentic AI workloads. The sixth-generation NVLink enables 3. This shift is pushing optical interconnect.
[PDF Version]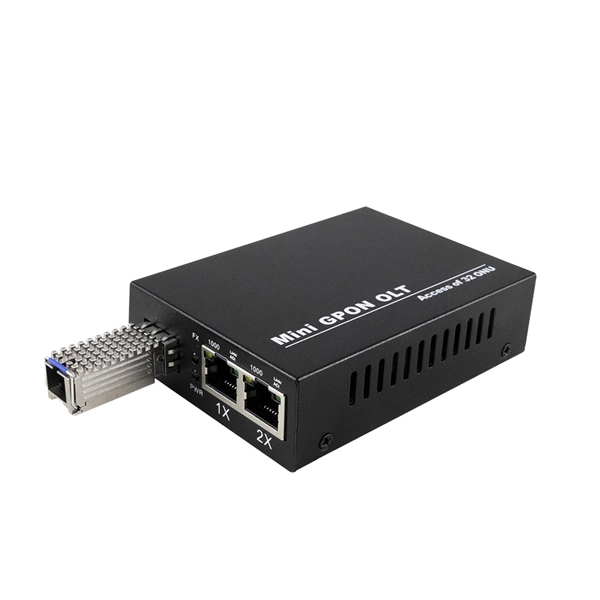
A complete tutorial for building a production-ready AI inference server on dedicated GPU hardware. The Model Context Protocol (MCP) is reshaping how AI applications connect to the world. Introduced by Anthropic in November 2024, MCP provides a standardized, open-source framework for Large Language Models (LLMs) to interact with external tools, data sources, and workflows. Covers framework selection, deployment, API design, monitoring, security, and scaling. While integrating a single ChatGPT API call is straightforward, running hundreds of AI agents in production, each potentially costing thousands of dollars. Design high-performance model serving systems that deliver consistent AI capabilities at enterprise scale. Prerequisites: This guide assumes familiarity with Kubernetes (pods, deployments, CRDs), basic GPU infrastructure concepts, and REST API design.
[PDF Version]
The next generation of AI servers pushes the bounds of computational power at the cost of increasing power consumption, requiring the use of liquid cooling. This forces servers to slow down (a process called throttling) or even shut down completely. We will dive deep into liquid cooling technologies. Direct-to-chip and immersion. Advanced AI chips are generating more heat in data centers, necessitating improved cooling solutions. These servers are equipped with input and output piping and require an ecosystem of manifolds, CDUs (cooling distribution) and. Schneider Electric's data center liquid cooling solutions are purpose‑built for AI workloads, GPU servers, and high‑density IT environments. Collecting heat and rejecting heat efficiently is the key to saving energy, decreasing time to value, and lowering total.
[PDF Version]Contact us for competitive quotes on any of our fiber optic products
Get a Quote